Super Model
以企业自有数据训练,经冻结测试集与专家盲评证明优于通用大模型后上线,并随真实调用持续迭代。Trained on company data, proven against general models on a frozen test set and blind expert review, then served and improved with real traffic.
- 授权Grant数据用途与处理区域已签署Use and processing region signed off
- 资料Data8,420 条历史文案,已去重脱敏8,420 past copies, deduplicated and masked
- 验收题Acceptance set240 道题封存,训练不可见240 items sealed, never trained on
- 评分标准Scoring与专家判断一致率 0.92Agrees with expert judgement at 0.92
- 训练Training第 2 版,基于 Qwen2.5-14BVersion 2, on Qwen2.5-14B
- 效果验收Acceptance胜出最强通用模型,成本为其 27%Beats the best general model at 27% of its cost
- 上线Go-liveent-partner-a-copy 可调用ent-partner-a-copy is callable
ent-partner-a-copy- 客服工作台Support desk
- 客户管理CRM
- 文案工具Copy tool
训练Train
以企业数据做监督微调与强化学习,多个开源底座并行比较。Fine-tuning and reinforcement learning on company data, with several open bases compared.
证明Prove
冻结测试集、独立评分器和专家盲评,生成不可修改的对比报告。Frozen test set, independent grader and blind review, in a report that cannot be edited.
上线Serve
注册为一个模型名,灰度、影子、回滚,由路由与通用模型协同调度。One model name, with canary, shadow and rollback, routed alongside general models.
迭代Improve
真实调用回流为训练数据,按信号触发再训练,版本持续提升。Real traffic returns as training data; signals trigger retraining and versions keep improving.
一个专属模型的生命周期The life of a dedicated model
从文件被外部模型牵走,到在企业边界内形成自己的模型、与通用模型逐项对比、接入现有系统,再到每一版持续变好。From documents pulled out to an external model, to a model of its own formed inside the company boundary, measured against general models, connected to existing systems and improved version by version.
律所条款识别演示,300 题封存考卷;响应为首字 P95;成本为每千次任务,示例价目。星环为示意。Law-firm clause demo, 300-item sealed exam; latency is P95 first token; cost per 1,000 tasks at sample prices. Rings are illustrative.
平台覆盖专属模型从数据到上线的全过程One platform from data to production
数据、评分、训练、报告、上线与迭代在同一个控制台完成,每一步都留有记录,任意一次训练都可以一条命令复现。Data, grading, training, reports, serving and improvement in one console. Every step is recorded and any run can be reproduced with one command.
总览Overview
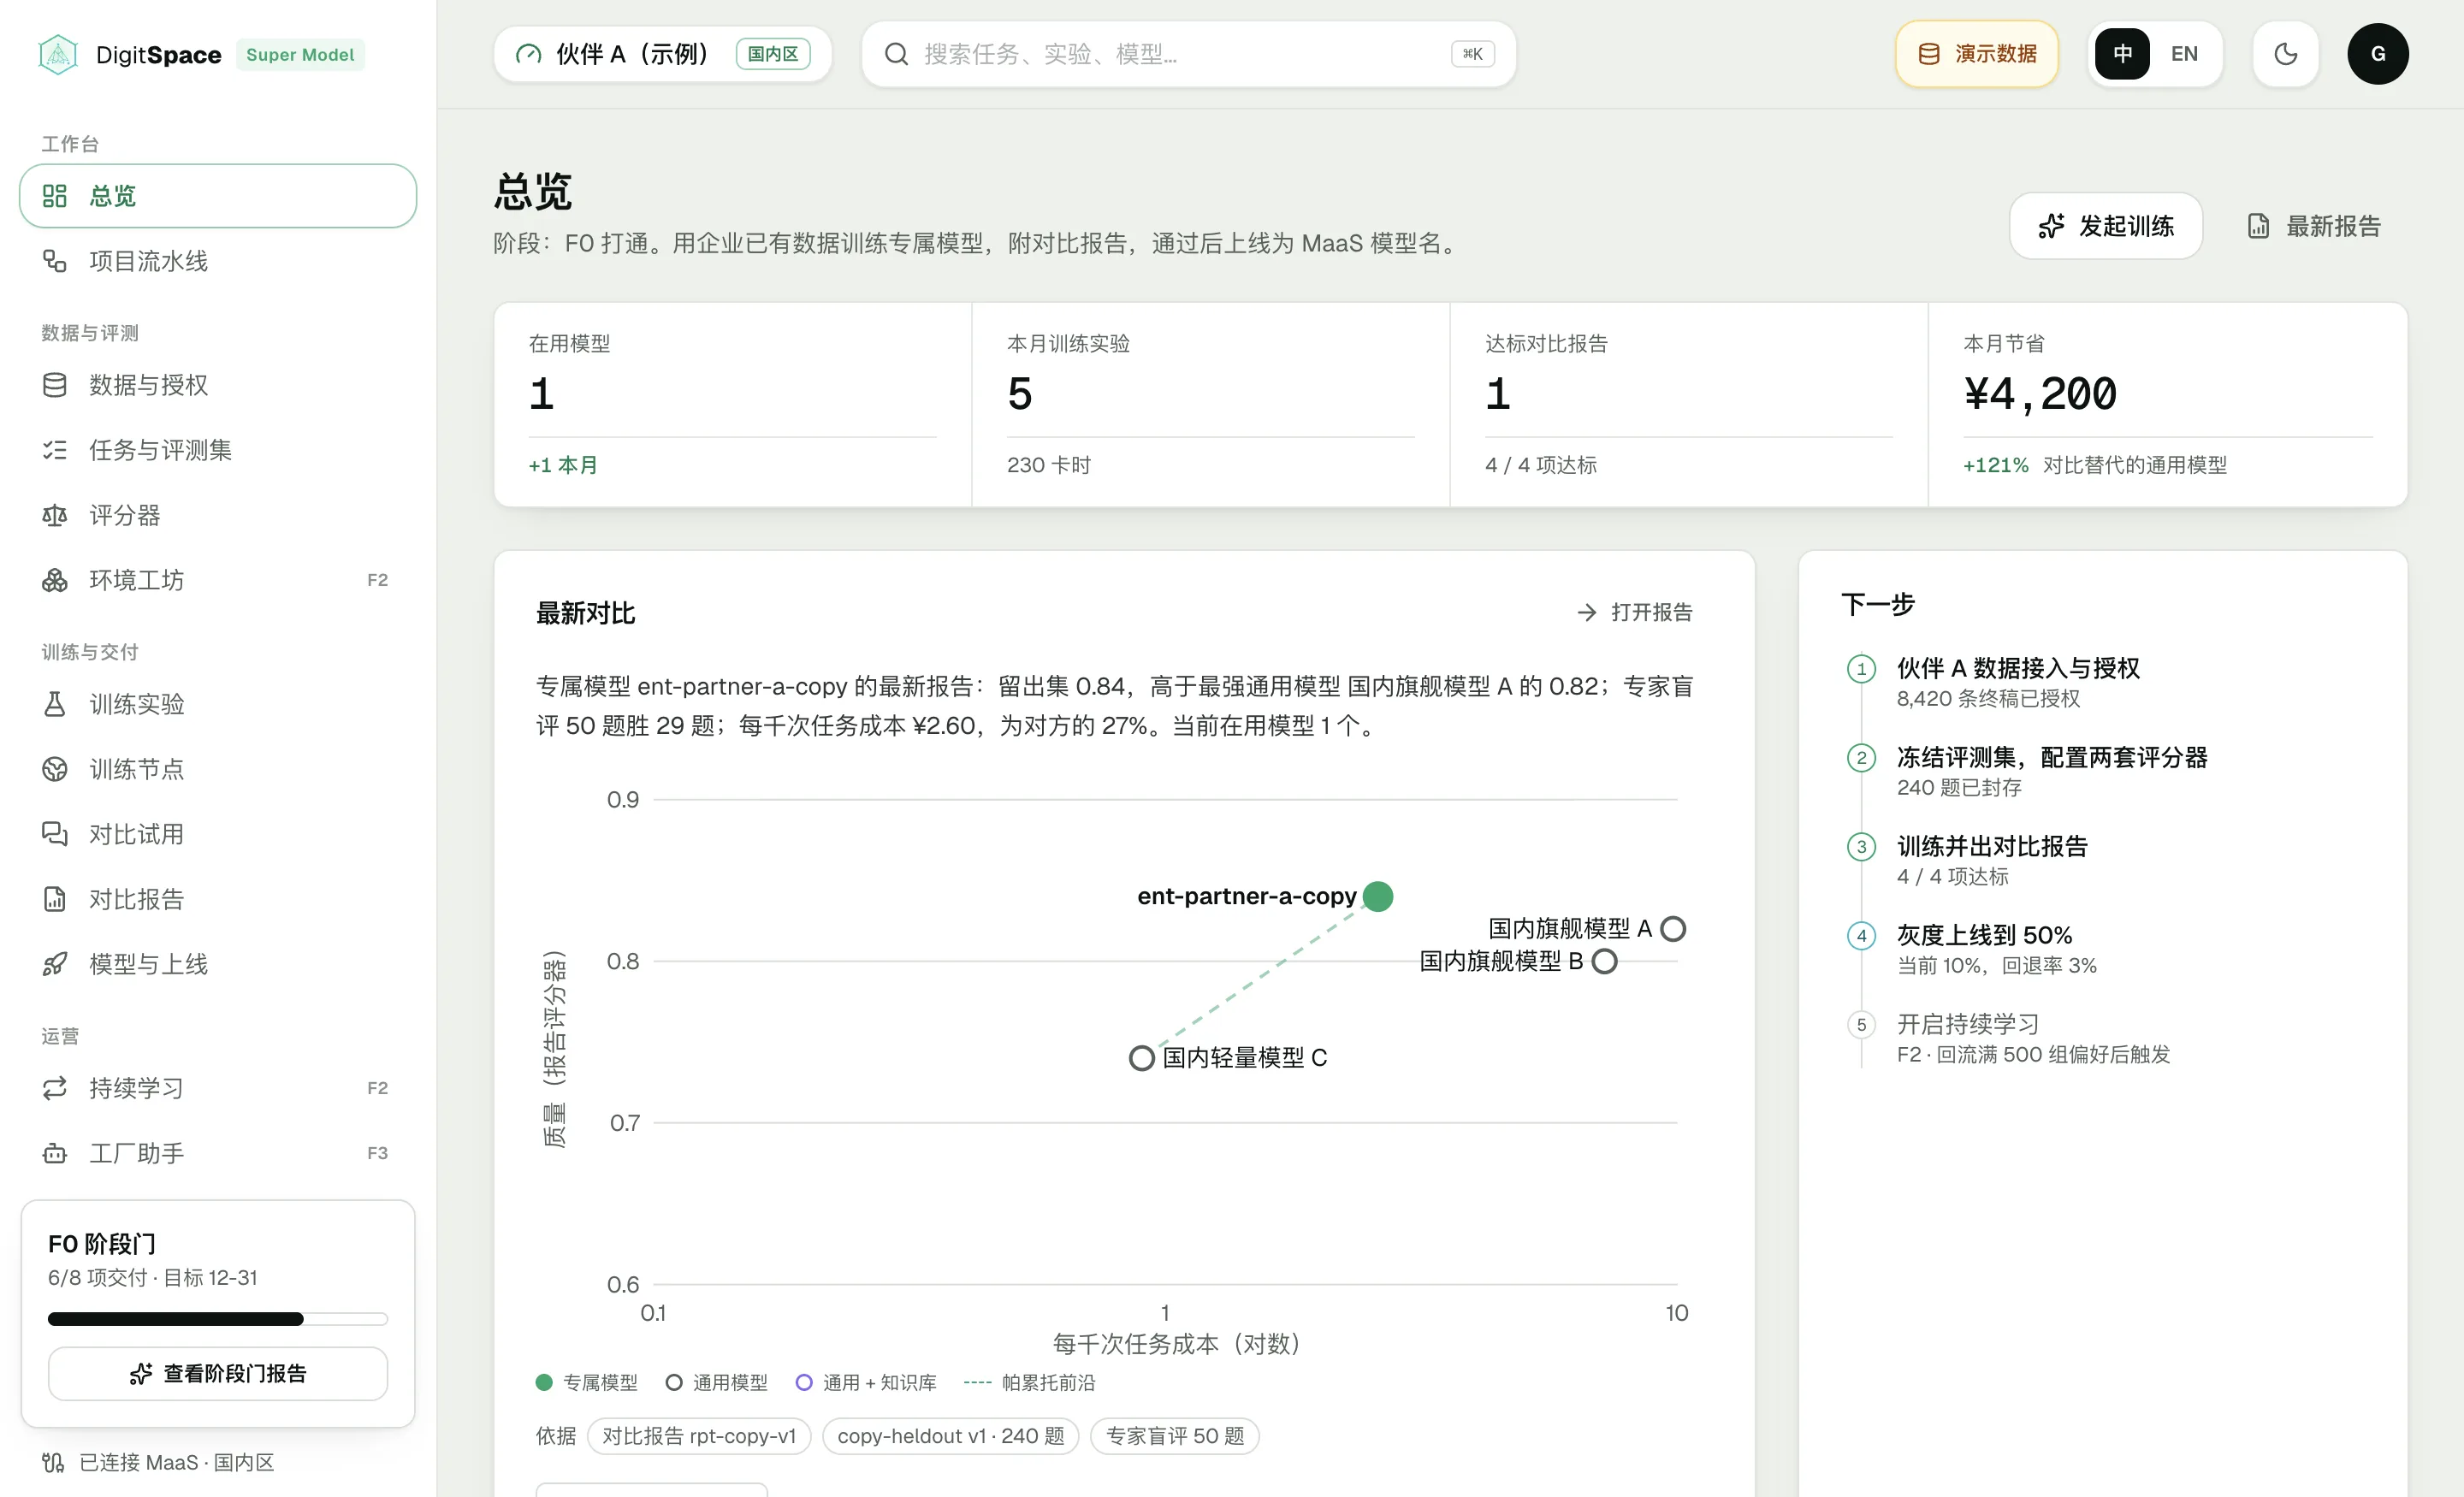
在用模型、训练实验、达标报告与节省金额集中呈现,并给出下一步建议。Models in use, runs, reports at parity and savings in one place, with suggested next steps.
训练实验Training
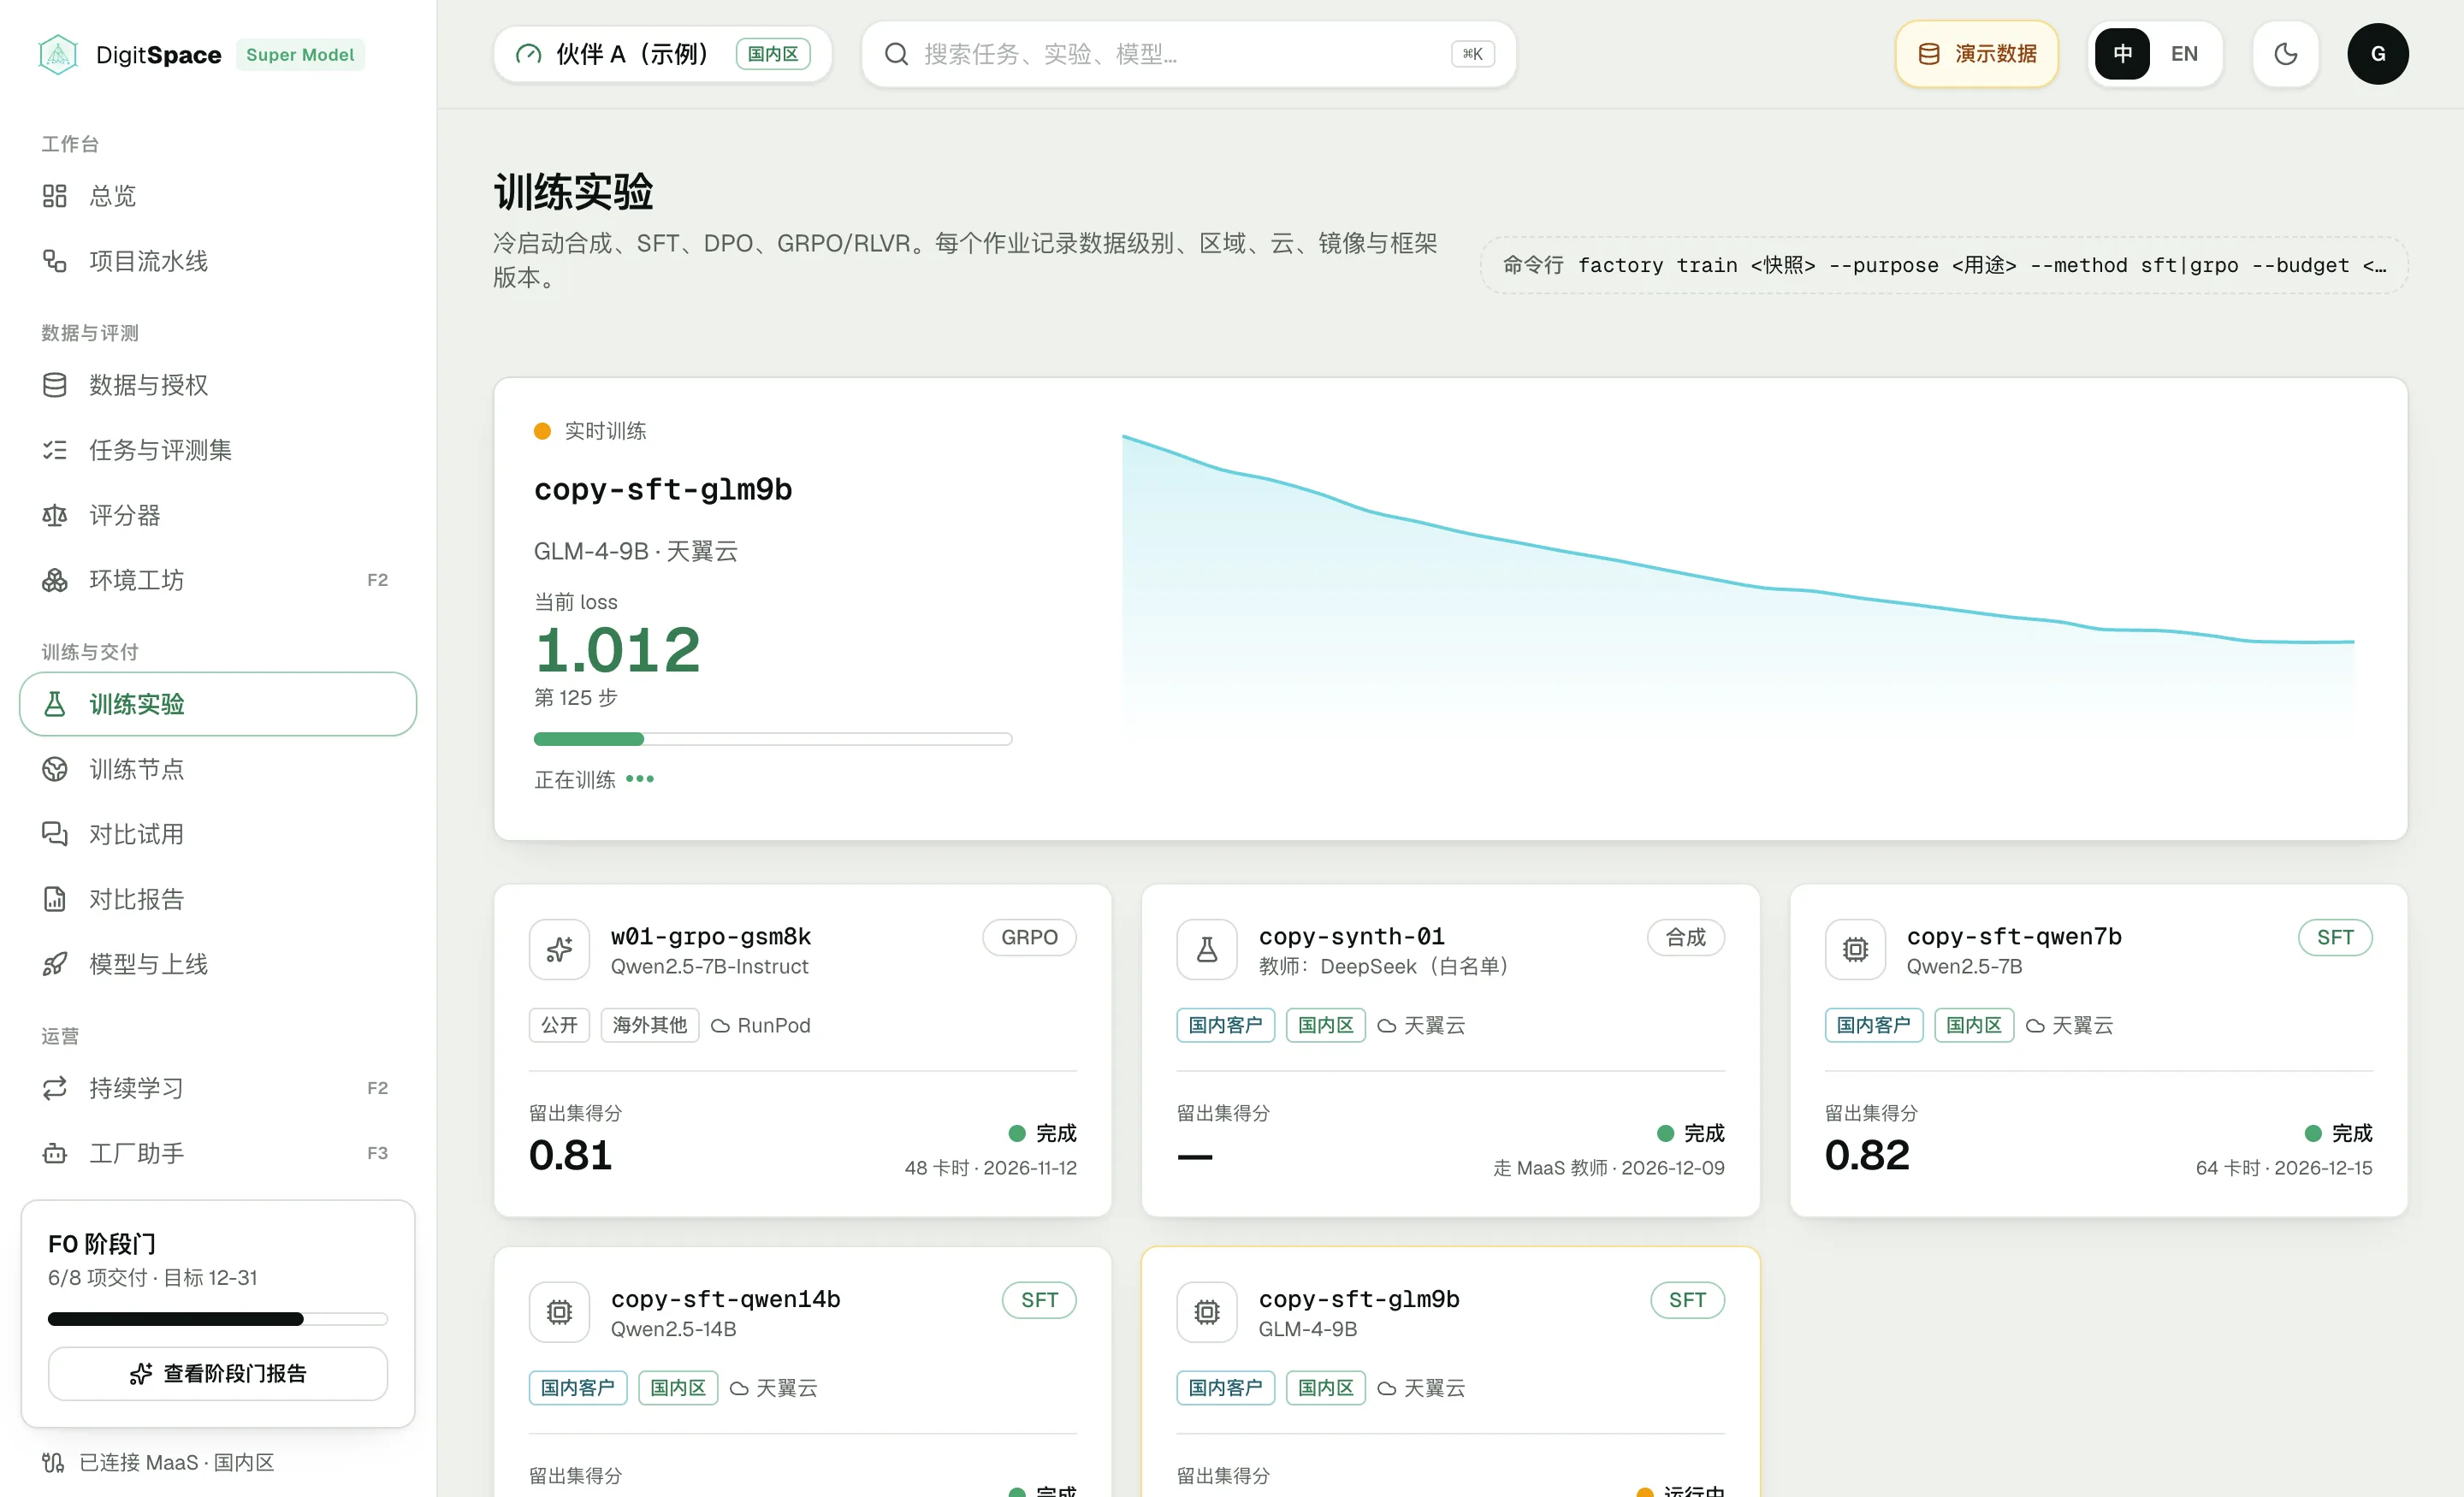
底座、数据快照、评分器、训练栈版本、卡时与花费完整记录,一条命令复现。Base, data snapshot, graders, stack versions, GPU hours and cost on record, reproducible with one command.
对比报告Reports
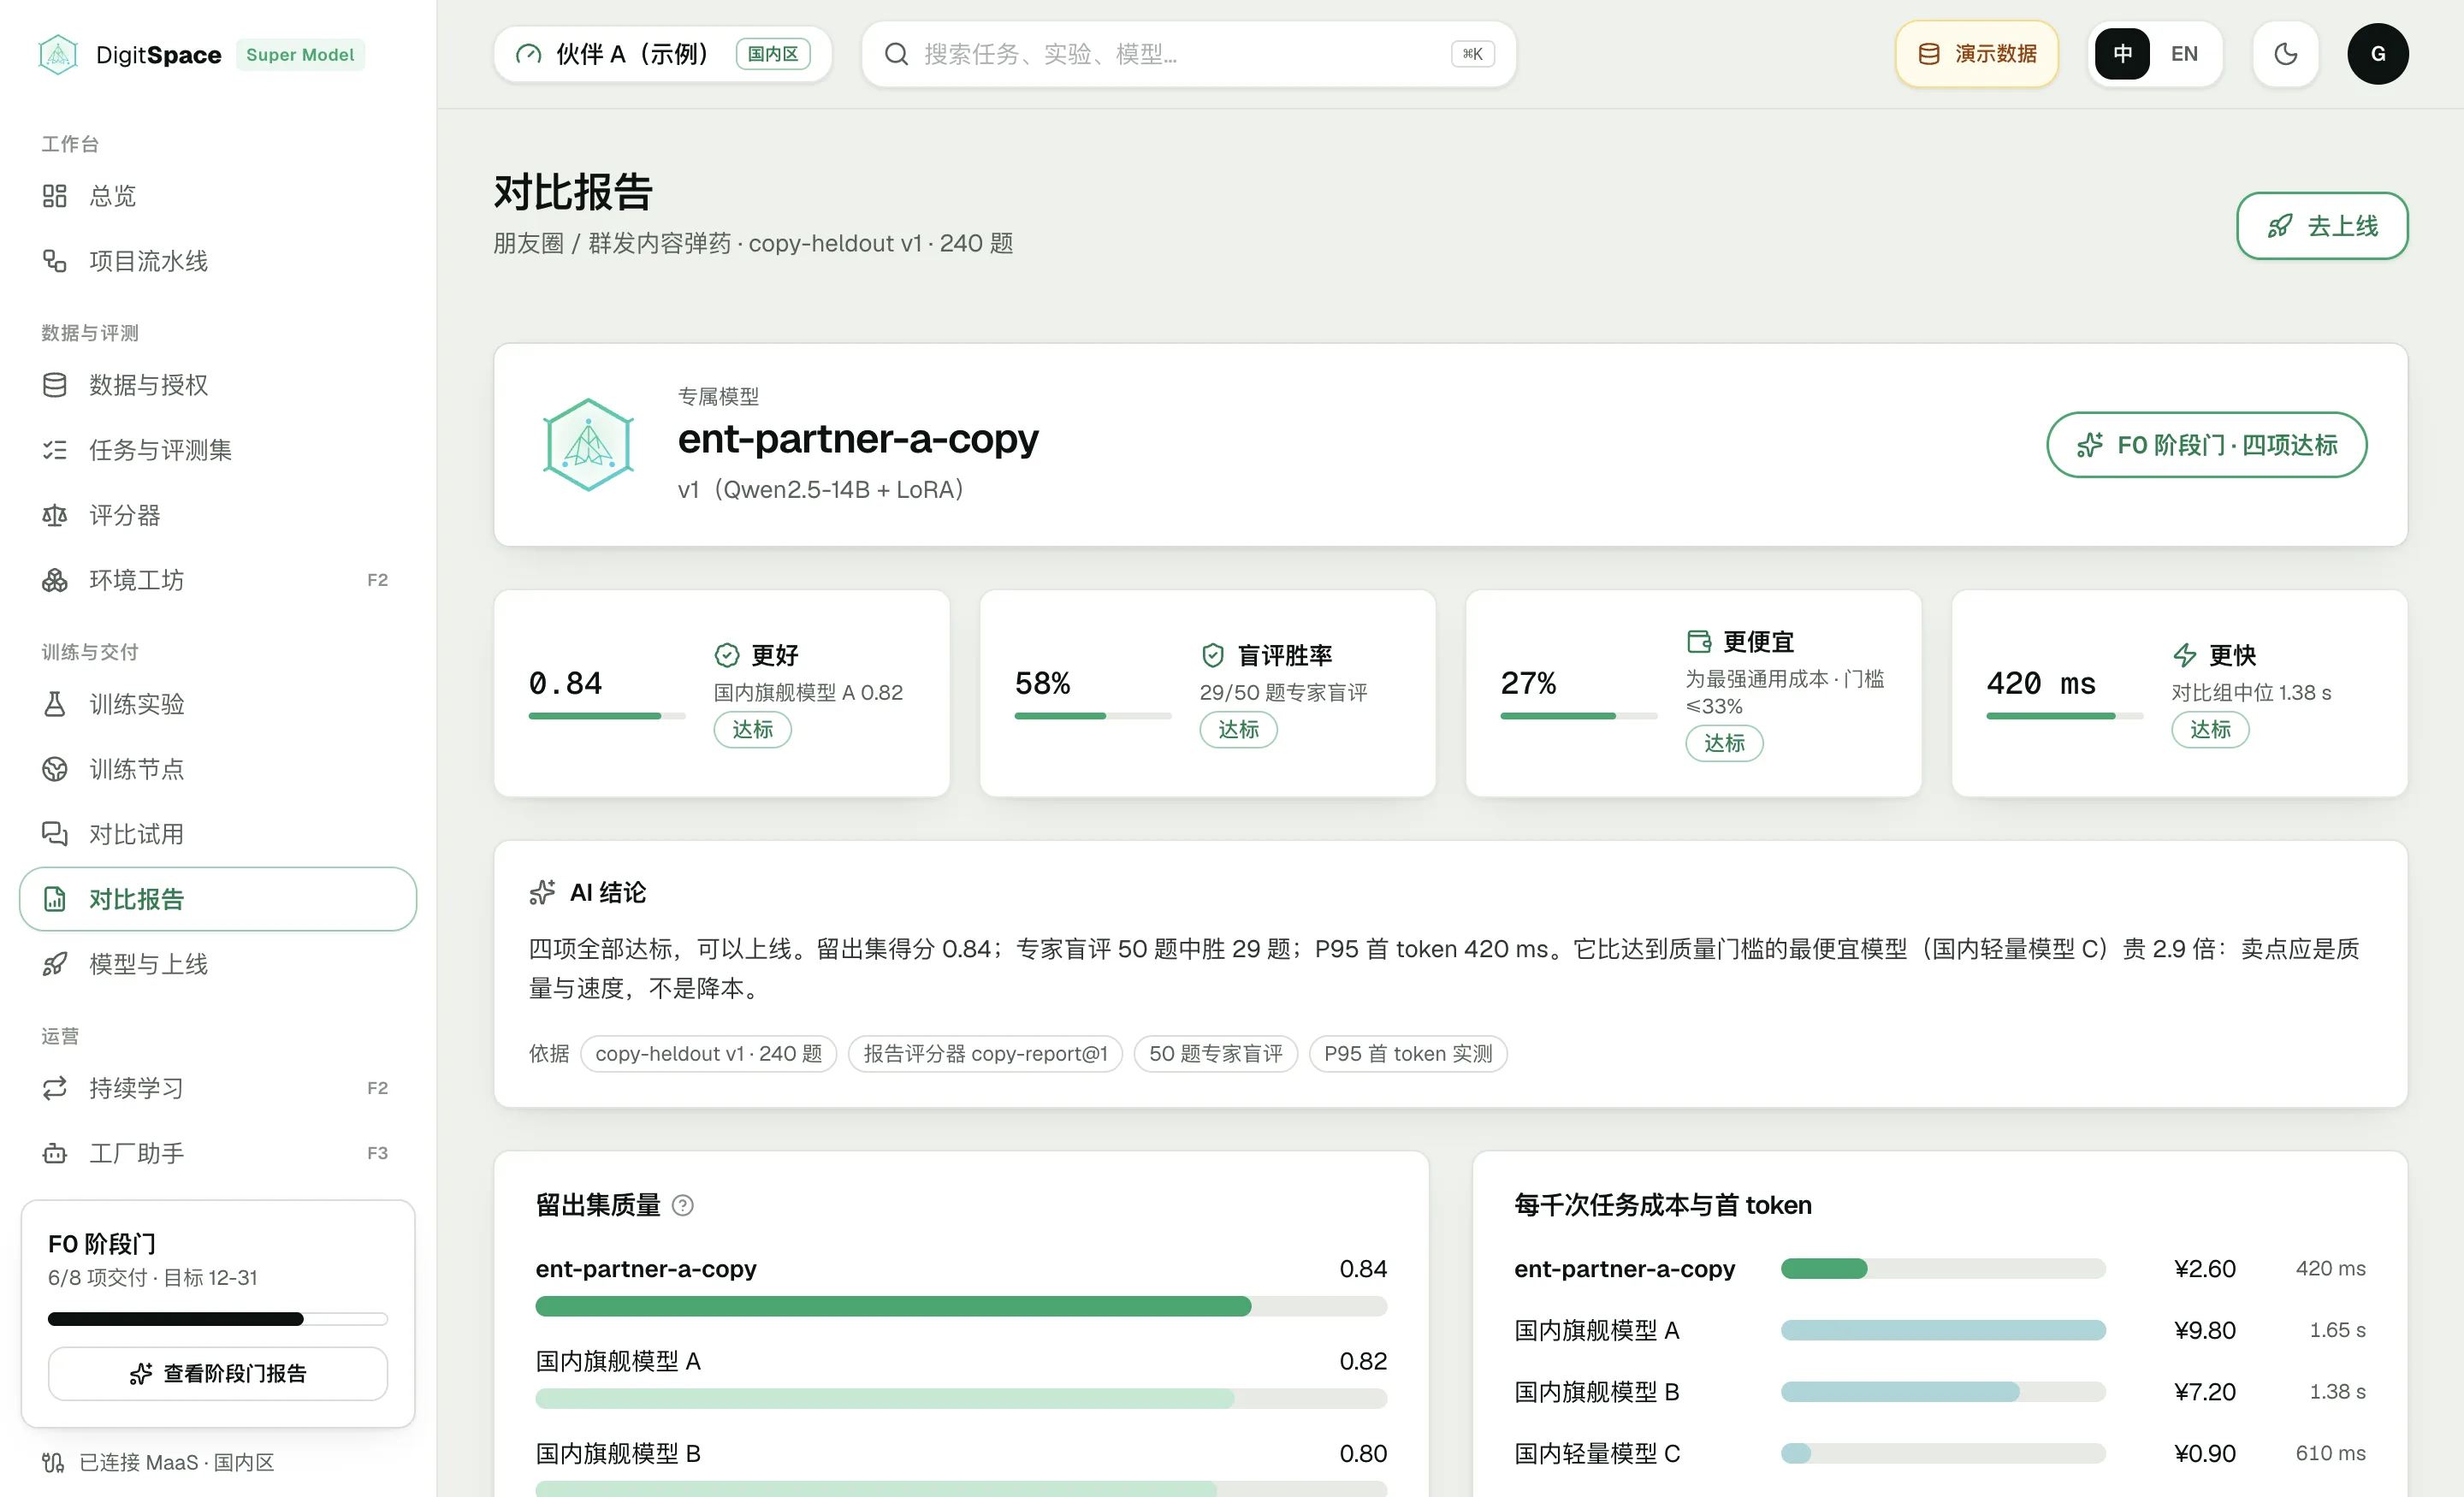
质量、盲评胜率、成本与速度四项判定,每一项都可追溯到依据。Quality, blind win rate, cost and speed, each traceable to its evidence.
模型与上线Go-live
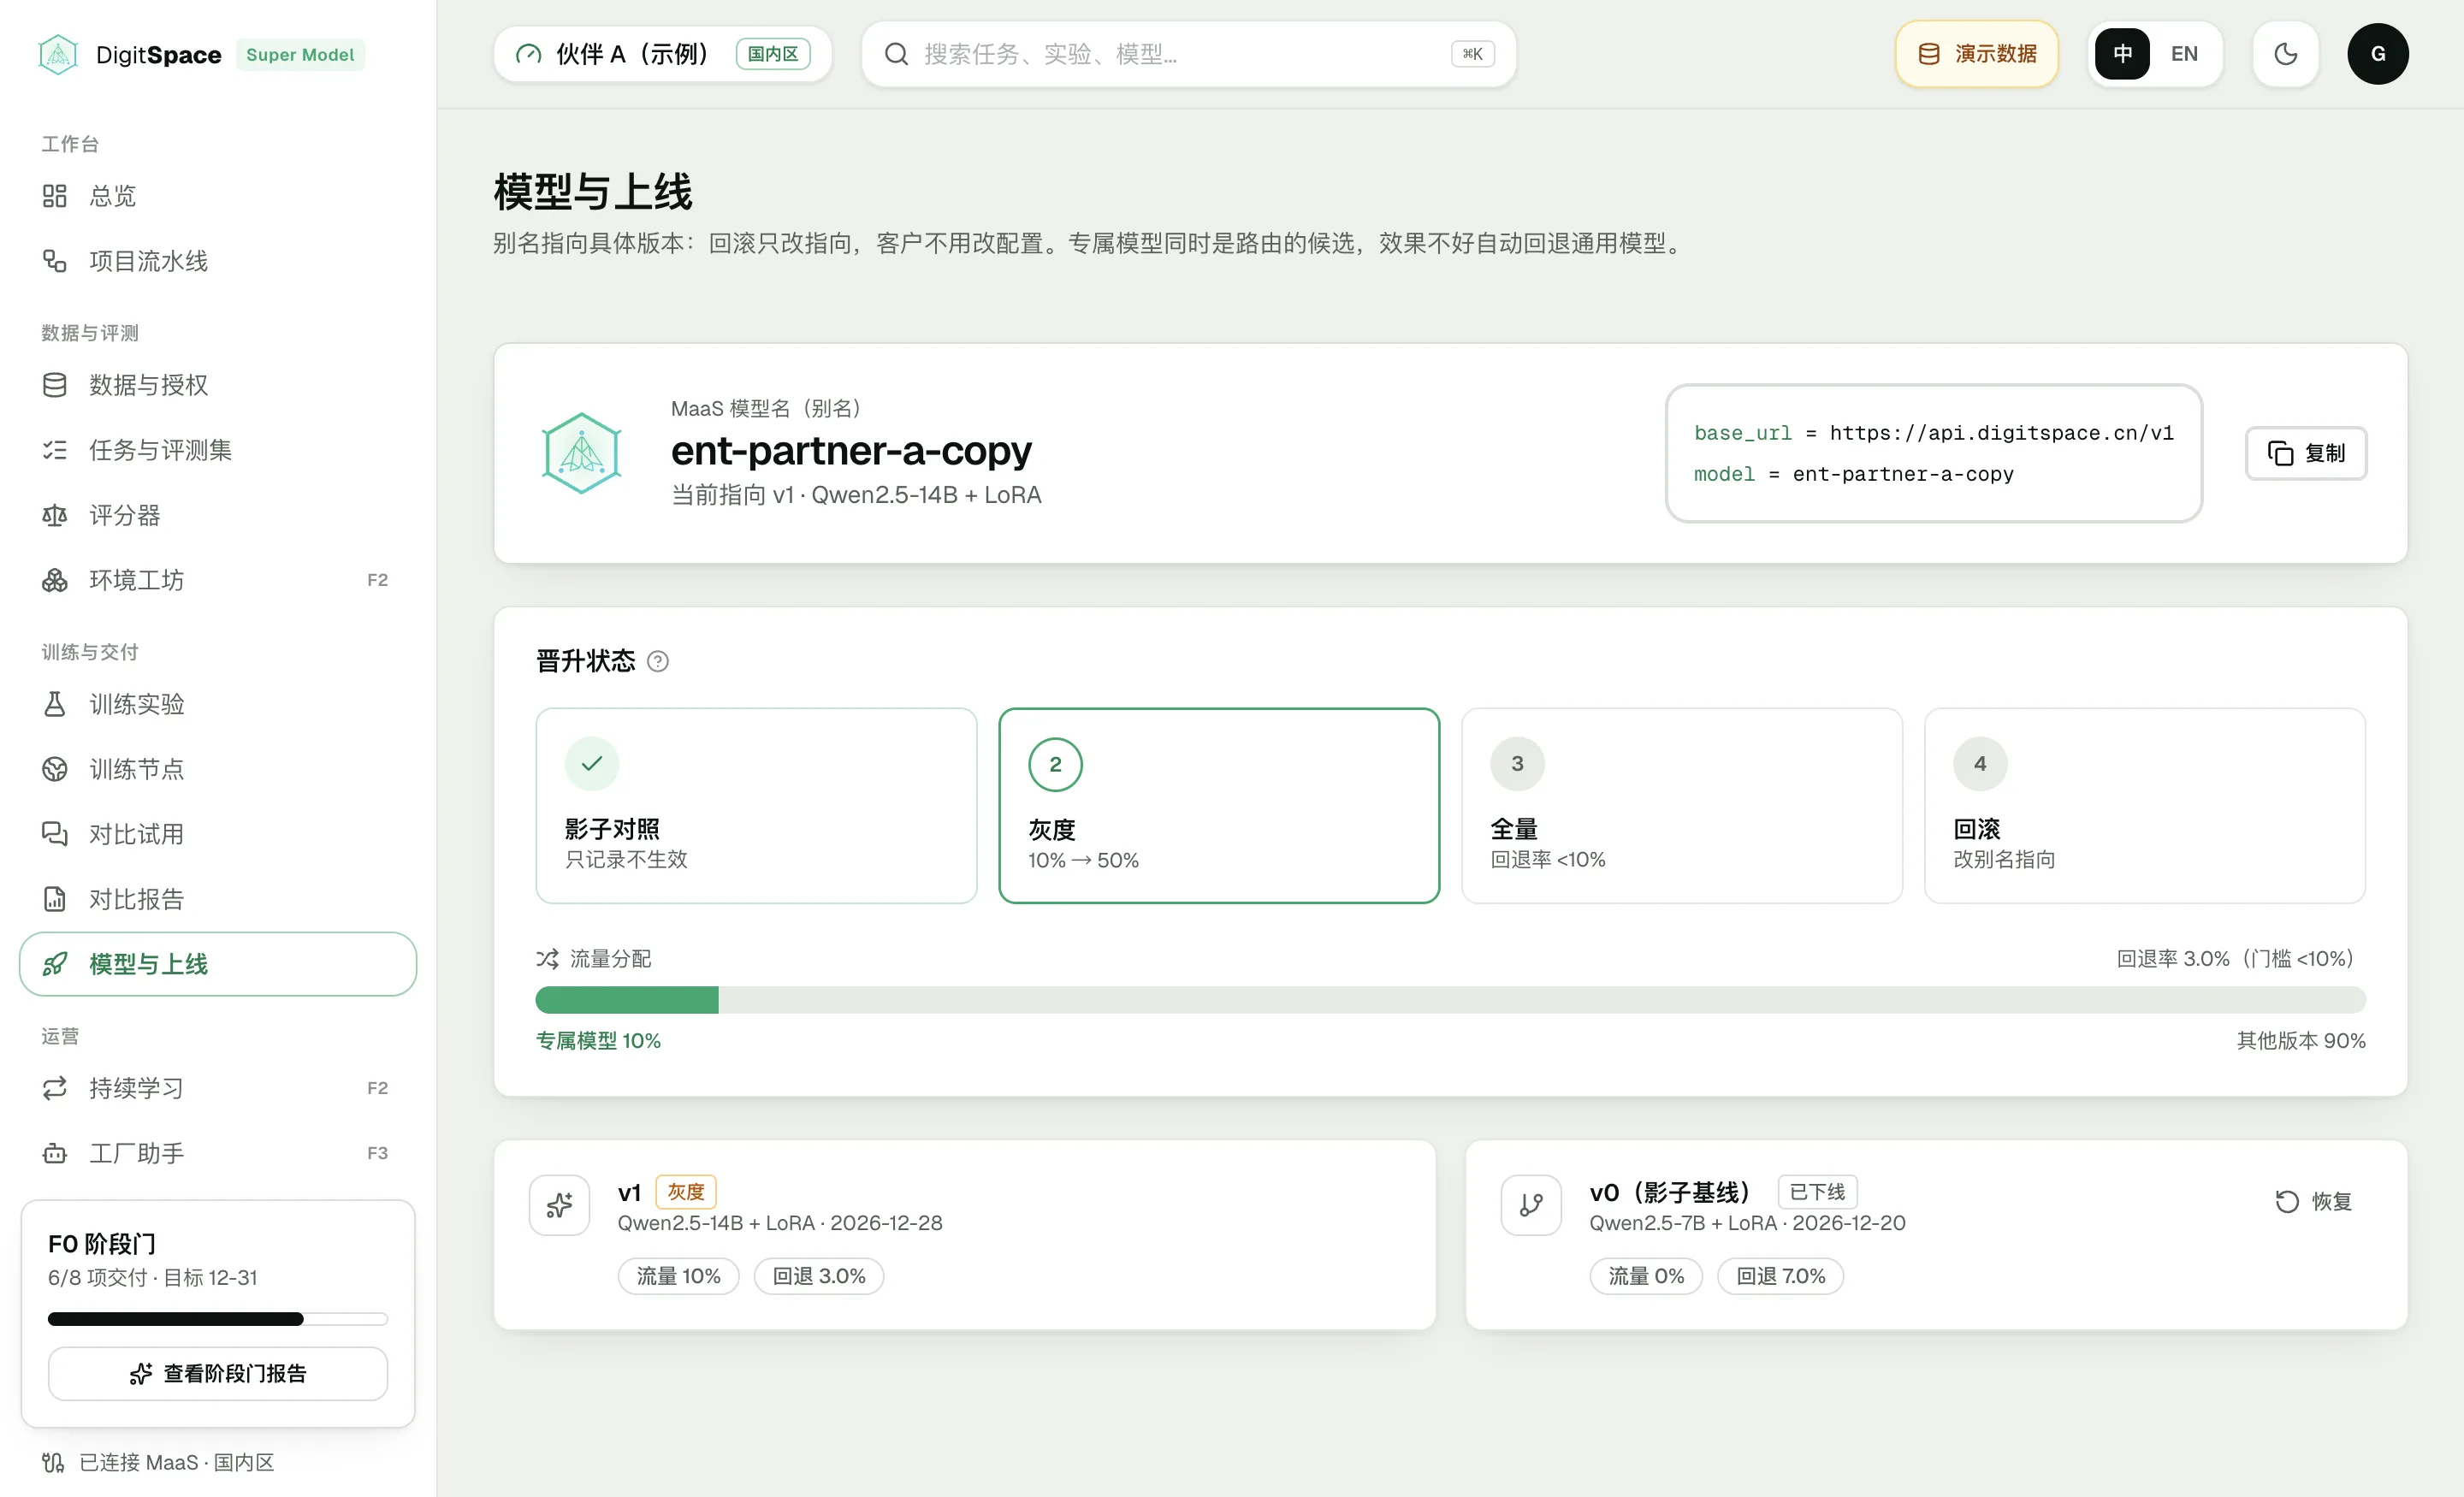
别名指向具体版本,灰度、影子与回滚只改指向,调用方无需改动配置。An alias points to a version; canary, shadow and rollback change the pointer and callers change nothing.
SuperLoop:生产在环的企业模型体系SuperLoop: an enterprise model system with production in the loop
训练信号来自生产环境中的路由裁决:同一请求由多个模型候选作答,业务方的采纳结果被记录下来,同时用作训练奖励、课程来源、评测基准和反作弊审计。模型按周期从这条信号流中更新。Training signal comes from routing verdicts in production: several candidate models answer the same request and the business outcome is recorded. That record serves as reward, curriculum, benchmark and anti-gaming audit, and the model is updated from it on a regular cycle.
RAL路由裁决学习Router-arbitrated learning以生产路由中的多模型对比作为组内比较,并用倾向得分纠正路由带来的选择偏差。Multi-model comparisons from production routing act as the group comparison, with propensity scores correcting routing bias.TAP教师锚定后验Teacher-anchored posterior蒸馏与强化学习统一为一个目标:证据充分处偏离教师,证据稀疏处回落到教师。Distillation and RL under one objective: move away from the teacher where evidence is strong, stay close where it is thin.FFC市场失灵课程Frontier-failure curriculum训练预算集中在所有候选模型都未被采纳的请求上。Training budget goes to requests where no candidate model was accepted.CaV合规即验证器Compliance as verifier数据放置、脱敏与出境规则进入训练奖励和报告评分器。Placement, masking and cross-border rules enter the training reward and the report grader.Gap评分器背离审计Hacking-gap audit对比训练评分、封存报告评分与真实采纳胜率三条线,度量评分器被钻空子的程度。Training score, sealed report score and real acceptance rate are compared to measure grader gaming.
建议从一个高频任务开始评估Start the evaluation with one frequent task
评估从数据体检开始:判断该任务能否训练、是否值得训练,并给出预期成本与回本周期。The evaluation starts with a data check-up: whether the task can be trained, whether it is worth it, and the expected cost and payback.